
Resolution and revisit describe what a satellite can collect. They say nothing about whether two of its observations belong on the same measurement scale.
Commercial Earth observation is still bought by the numbers: resolution, revisit, coverage and latency. These tell buyers whether a system can see the right area, at the right scale and often enough for the job. They say far less about whether the measurements are accurate, stable or comparable across satellites and time.
That distinction was easier to overlook when analysts inspected images one at a time. It is harder to ignore when continuous data feeds are used to detect crop stress, map wildfire damage or flag changes across national territory. The customer is relying on a measurement record.
A new joint framework from NASA, the European Space Agency and the USGS addresses what the specification sheet leaves out. The Joint Earth Observation Mission Quality Assessment Framework asks whether quality claims are documented, calibration is traceable, uncertainty is characterized, processing is transparent and performance has been independently validated.
The framework supports NASA’s Commercial Satellite Data Acquisition Program and ESA’s Earthnet Data Assessment Project. Its public release also lets other buyers examine how such claims are tested. The framework remains advisory: conformity is voluntary and not legally binding.
What Resolution and Revisit Do Not Show
A five-meter pixel describes the nominal spatial sampling of an image. It is not an accuracy rating. Daily revisit describes how frequently an observation may be possible and whether Tuesday’s measurement can be compared reliably with Monday’s is a separate question entirely.
Coverage and latency carry the same limitation. A provider may collect the geography and deliver it quickly while leaving more consequential questions unanswered. Are reflectance values tied to a recognized physical reference? Do the satellites in the constellation measure consistently? Can users identify observations affected by cloud, shadow, saturation or other quality problems?
The answers determine what the product can support. A natural-color image may tolerate small radiometric differences that would undermine a system tracking gradual vegetation decline. A level of uncertainty acceptable for flood mapping may be unacceptable for detecting early crop stress or subtle mineral signatures. The same dataset can be more than adequate for one and unusable for the other, which is why ‘high quality’ cannot be judged in the abstract. It has to be judged against the measurement, its uncertainty and the decision it is meant to support.
From Pixel to Product
Every delivered pixel has a history. It begins with an instrument in orbit and passes through calibration, atmospheric and geometric correction, cloud screening, processing and distribution before reaching the user.
Providers should be able to show how the sensor’s digital output is converted into radiance, reflectance or temperature. They should also document how the instrument was characterized before launch and how its performance is monitored afterward.
In a constellation, each instrument must be characterized individually, even when every instrument is built to the same design. Differences in detector sensitivity, spectral response or geometric alignment can become visible when observations from several spacecraft are combined into one time series.
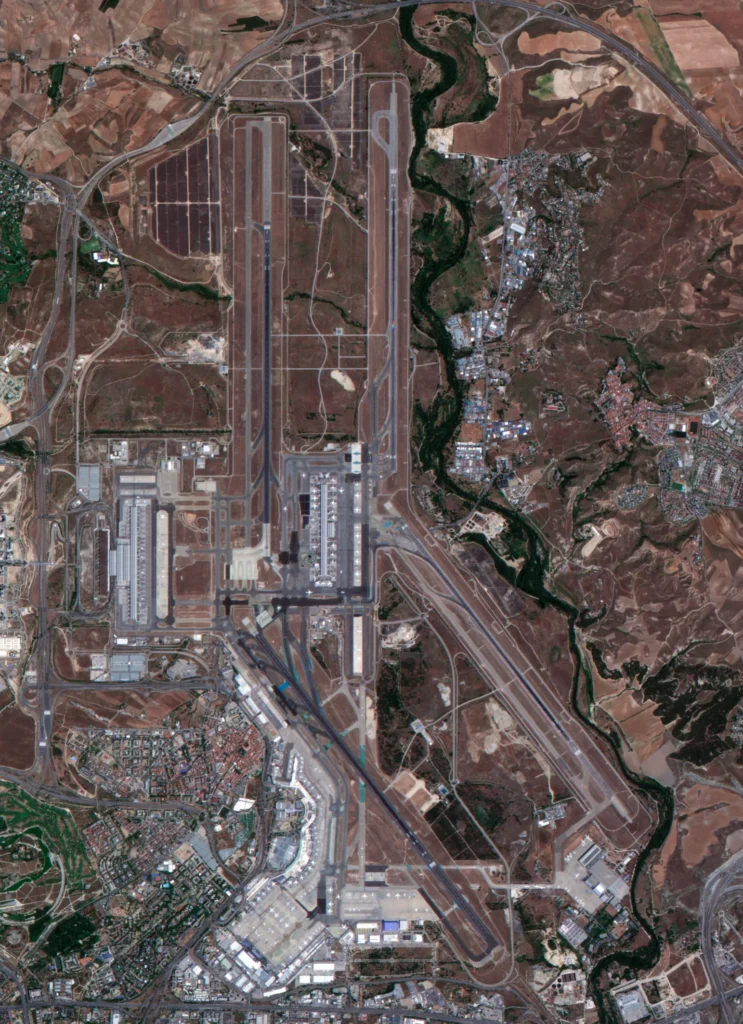
EarthDaily AiRD image of Madrid–Barajas Airport, Spain, acquired June 17, 2026.
Spectral response is one place those differences can appear. Two bands carrying the same near-infrared label do not necessarily measure exactly the same wavelengths or respond to them in the same way. That difference can carry into a vegetation index, or alter a burn-severity calculation built on near-infrared and shortwave infrared together.
Processing must account for these effects. Surface reflectance requires atmospheric correction. Change detection requires reliable cloud and shadow screening. Products assembled from multiple instruments may also need corrections for viewing geometry and spatial alignment before the observations can be treated as one record.
Comparability is not a byproduct of shared specifications. It has to be built and demonstrated, not assumed from a similar pixel size or shared constellation label.
What the Evidence Must Show
“Calibrated and validated” is a claim, not the evidence behind it. Buyers need to know what was tested, how it was tested and what the results showed.
The joint framework separates the provider’s documentation from detailed validation of the resulting data. For a buyer, that becomes two questions for a vendor: can you show your process, and can you show that it worked. A vendor who can only answer the first has described an intention, not a result.
For a constellation, the number worth asking for is never the fleet average alone. The outliers and the weakest-performing satellite are where an automated pipeline actually breaks.
A provider with a credible answer to “calibrated and validated” should already be able to show whether performance was evaluated against independent references, whether results are reported by satellite and spectral band, and whether radiometric and geometric stability is tracked over time.
That evidence should show the distribution of results, including outliers, along with the uncertainty that accompanies the measurements and how anomalies and known limitations are communicated. Each observation should be traceable to its source instrument and processing version, with a clear answer for what happens to the historical record when calibration or processing changes.
A buyer’s job is not to extract this. It is to notice when a provider cannot produce it.
Why AI Raises the Bar on Data Quality
As AI becomes part of more workflows, the data feeding it needs to be measurement-grade to begin with, and traceable back to its source when something still slips through. A model only learns from the values it receives, and it cannot tell a real signal from an error introduced by the sensor. A satellite that drifts out of calibration, or measures differently from the rest of its fleet, can teach the model that the drift itself is crop stress or forest loss.
That kind of error can stay hidden for a long time, as long as the data feeding the model comes from a consistent mix of sensors. It tends to surface later, once a new satellite joins the constellation or an older one gets recalibrated.
Metadata, provenance and versioning are therefore part of the quality record: which satellite collected an observation, which processing version produced it and what quality conditions applied. An “AI-ready” label does not answer those questions.
Before any of this data trains or feeds a model, the provider should already be able to show where it lands against the joint framework’s documentation review and detailed validation categories. An AI system cannot flag an unexplained shift in its inputs. A provider’s own records are the only place that traceability can come from.
Resolution and revisit still belong on the spec sheet. Accuracy, consistency, traceability and uncertainty belong in the buying decision.