Census income maps are essential infrastructure for public policy, retail planning and social research. They are also snapshots. By the time a decennial census has been cleaned, mapped and embedded in decision-making, neighborhoods may already be changing faster than the official data can show.
A new study asks whether a familiar commercial map can help fill that gap. Using points of interest retrieved from Google Maps and income data from Brazil’s 2022 census, the researchers trained machine-learning models to estimate monthly household reference income across census sectors in São Paulo. The result is not a substitute for official statistics. It is a useful test of how the institutional landscape recorded by a mapping platform can act as a proxy for local socioeconomic structure.
The problem with ten-year snapshots
Income estimates are unusually difficult to update between censuses. Surveys can provide timely indicators at national or regional scale, but their samples are rarely dense enough to describe small neighborhoods. Satellite imagery can identify buildings, roads and physical change, yet wealth is not always visible from above. Administrative records can be powerful, although access, consistency and privacy constraints limit their reuse.
Points of interest offer a different signal. Restaurants, clinics, schools, banks, shops and public services encode how a place functions. Their mix can reflect purchasing power, employment patterns, public investment and accessibility. Because commercial mapping platforms are updated more often than censuses, POIs could provide a relatively current layer for estimating where socioeconomic conditions may have shifted.
Reading the institutional landscape
The study links Google Maps POIs to census sectors and represents each area through the composition of nearby place categories. Rather than assuming that a single amenity indicates affluence or deprivation, the models learn patterns across the broader local mix. The authors test dimensionality-reduction techniques, including principal component analysis and non-negative matrix factorization, before using regression models to estimate income.
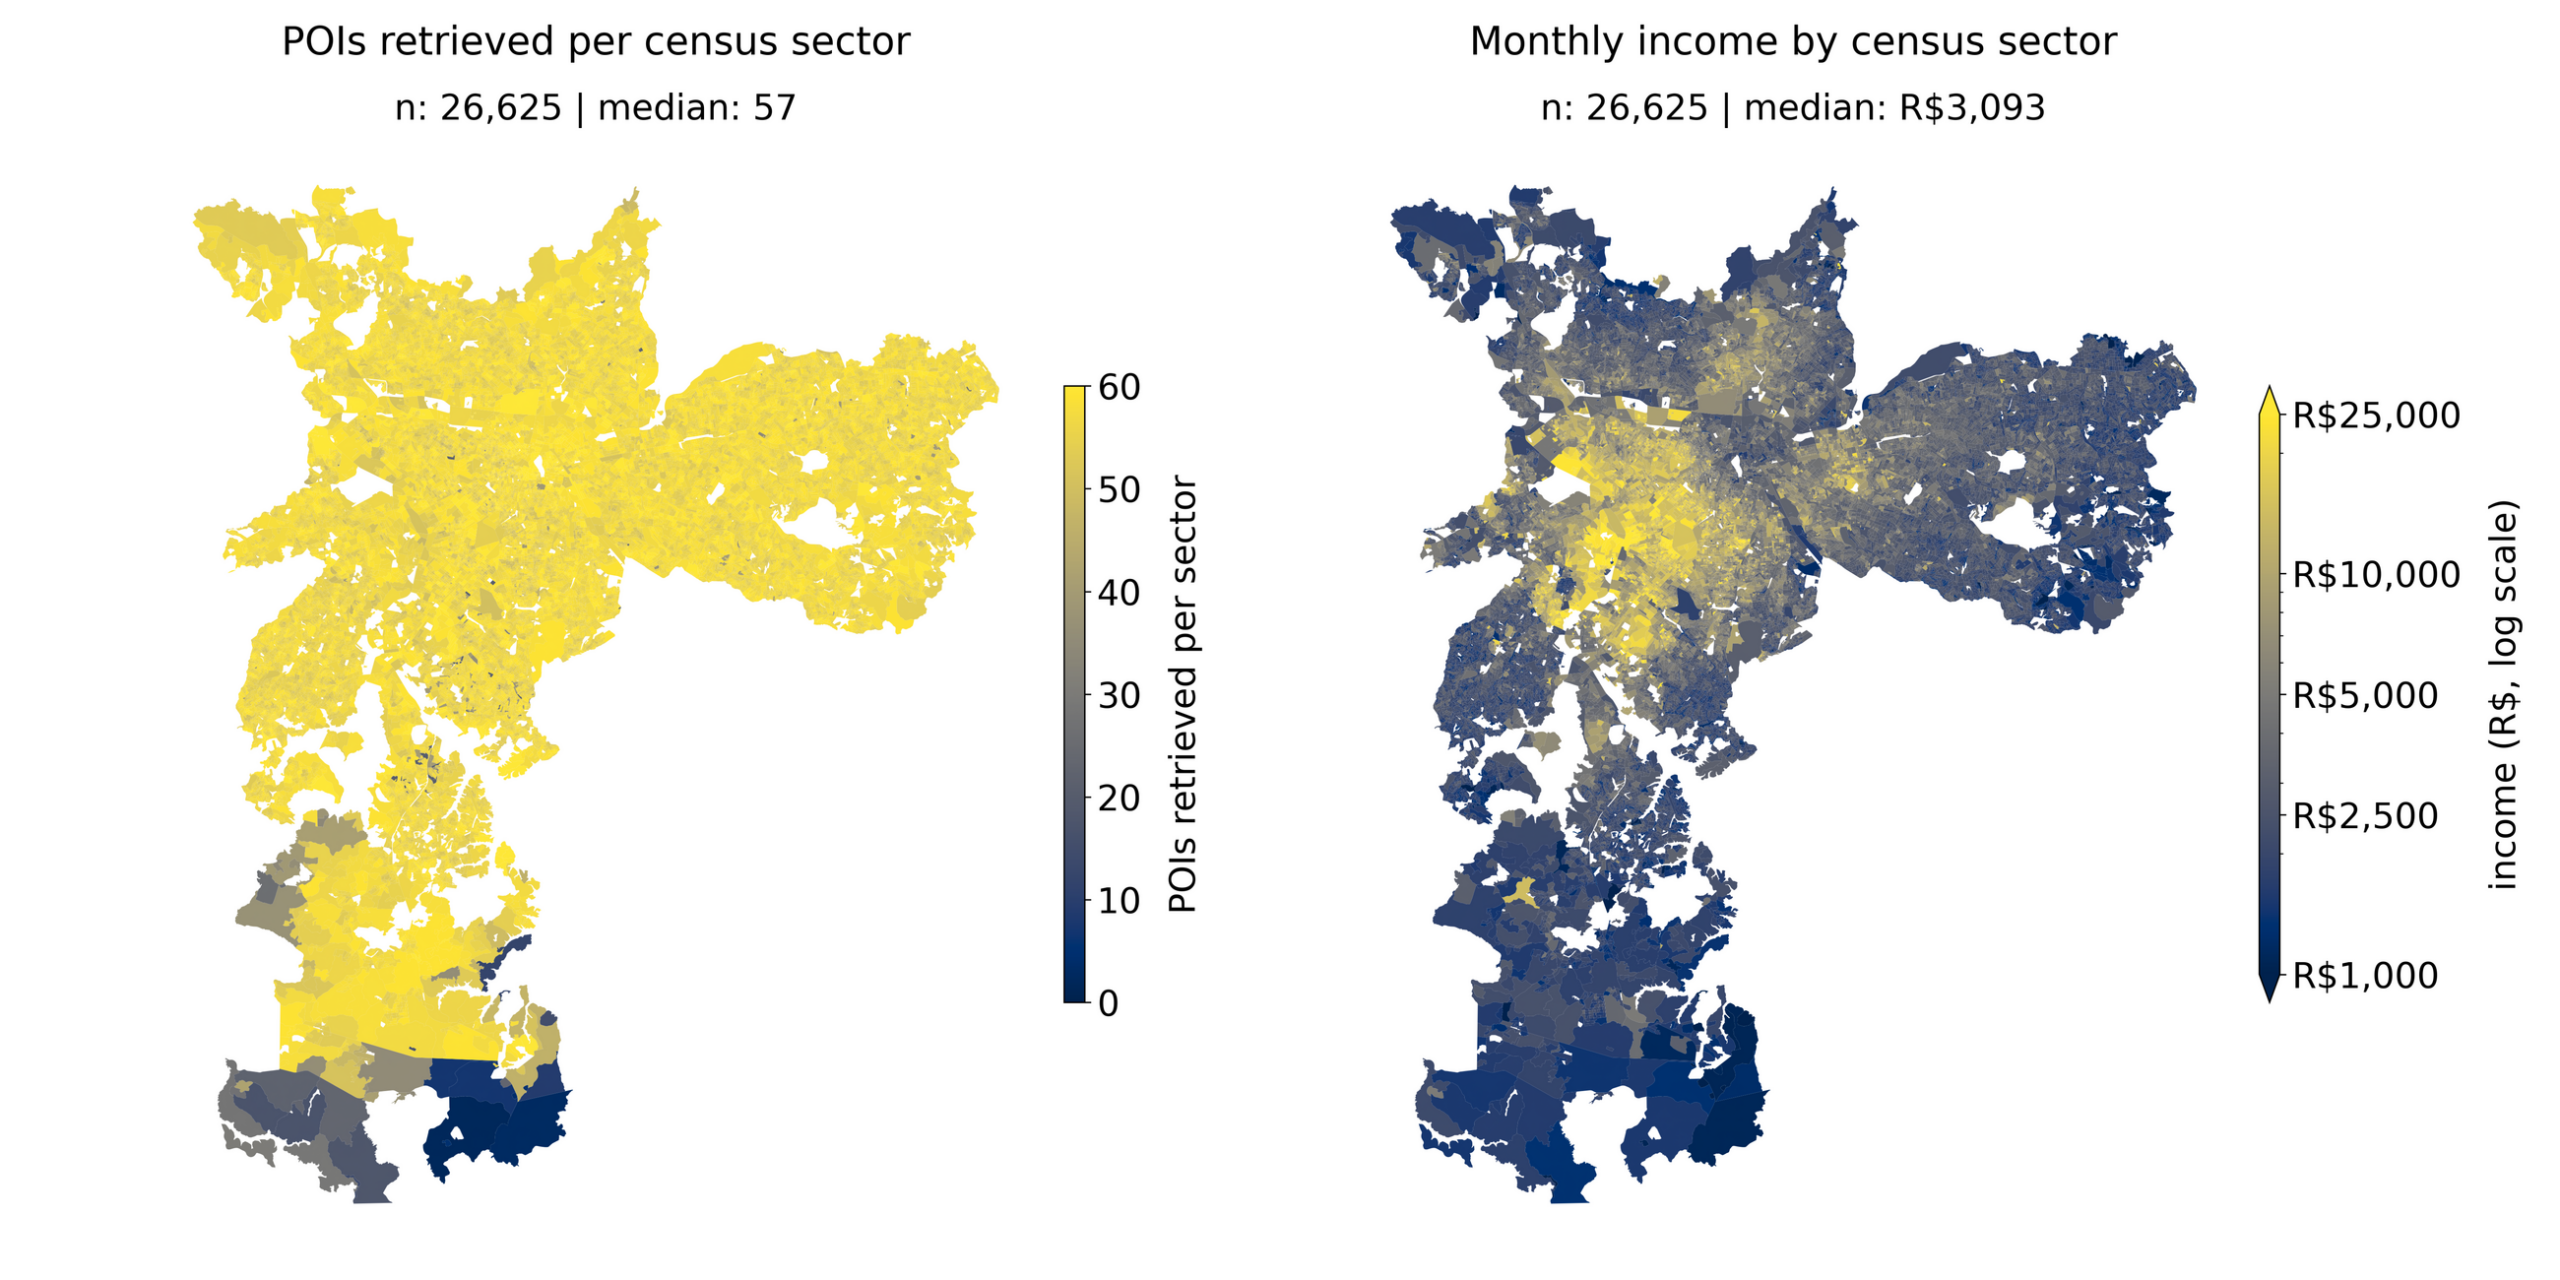
This framing matters. A POI database is not merely a directory of destinations; at sufficient scale, it becomes a representation of urban economic organization. The research suggests that commercially maintained location data can reveal a substantial share of neighborhood-level income variation, even without direct access to transactions, mobile-phone traces or household records.
Spatial validation makes the result more credible
Geospatial prediction is vulnerable to leakage. If nearby sectors are split randomly between training and test sets, a model can appear accurate partly because neighboring places resemble one another. That is useful for interpolation, but it can overstate performance when the real task is to generalize into locations the model has not effectively seen.
The authors address this with spatially structured validation, dividing the study area into geographic blocks rather than relying only on random samples. This is one of the paper’s most important methodological choices. It makes the results more relevant to operational use, where agencies and companies may want to estimate conditions in areas with limited reference data rather than merely reproduce patterns next door.
What the model appears to be learning
The strongest signal comes from combinations of places, not from a universal rich-place or poor-place checklist. Financial services, specialized retail, health care, education and leisure may all contribute, but their meaning depends on context and co-location. A dense commercial center can contain amenities associated with high spending while serving residents from much poorer surrounding districts.
That ambiguity is why the study should be read as location intelligence rather than automated socioeconomic labeling. The model identifies statistical associations within São Paulo’s urban system. It does not establish that a particular venue causes income, nor that the same POI composition would carry the same meaning in another city.
The model is weakest where mistakes may matter most
The error maps show that performance is not evenly distributed. High-income sectors can be difficult to estimate, and places with sparse, atypical or informally documented economic activity may also be poorly represented. Google Maps coverage is shaped by business visibility, user contributions and platform policies. Informal enterprises and low-digital-presence services can be missing even when they are important to local livelihoods.
That creates an important equity question. If a model is deployed to allocate services, prioritize inspections or target investment, systematic underrepresentation of informal or rapidly changing neighborhoods could reinforce the same blind spots the system is intended to reduce. Performance averages are therefore less informative than knowing where, and for whom, the model fails.
A four-year temporal mismatch
The study also contains a temporal limitation that deserves attention. The target income layer comes from the 2022 census, while the Google Maps POIs were retrieved later. The model is therefore relating two urban snapshots separated by several years. In stable neighborhoods that may be acceptable. In areas affected by redevelopment, business turnover or new transport investment, the mismatch can blur the relationship.
This does not invalidate the experiment, but it changes the claim. The paper demonstrates that recent platform POIs contain information associated with earlier census income. A production monitoring system would need repeated POI snapshots, versioned collection procedures and newer ground truth to show that it can reliably detect change between censuses.
A complement, not a replacement
For public agencies, the most promising use may be as an early-warning or prioritization layer. A POI-based model could flag sectors whose commercial and institutional profile has changed enough to justify a survey, field visit or administrative-data review. For businesses, it could support market screening in places where official small-area statistics are outdated, provided uncertainty and coverage bias remain visible.
The strategic lesson reaches beyond Google Maps. Location platforms increasingly function as privately maintained observations of urban life. Their data can supplement slow official systems, but they also introduce dependence on opaque collection rules, shifting taxonomies and licensing conditions. Reproducibility becomes an operational issue: a model trained today may be difficult to recreate if the platform’s inventory or access method changes.
The research is currently an arXiv preprint and should be treated as an early result rather than a validated production recipe. Its value lies in demonstrating a practical bridge between location intelligence and official statistics—and in making the limitations of that bridge visible.
How do you like this article? Read more and subscribe to our monthly newsletter!

#Science
Next article
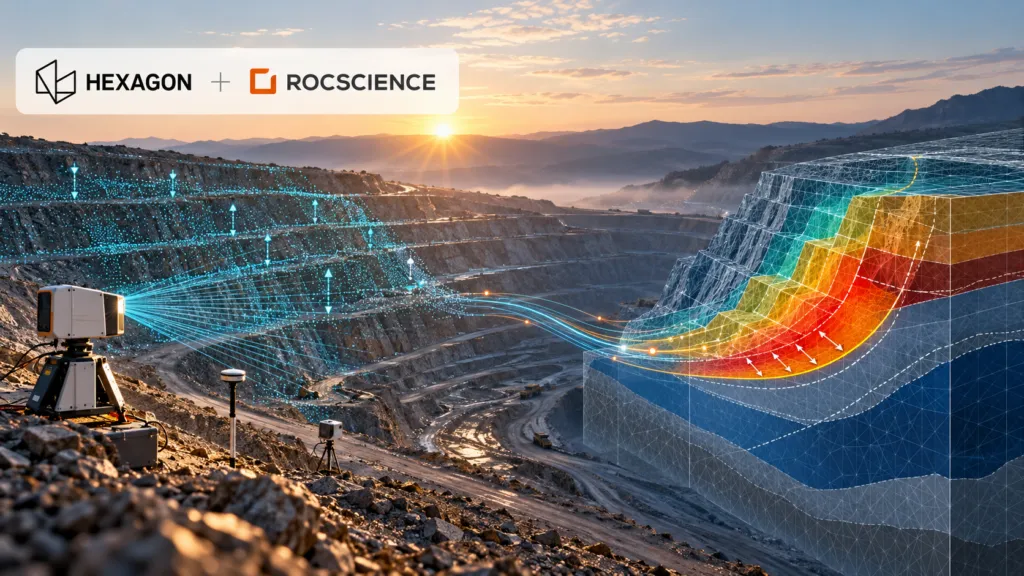
Hexagon has agreed to acquire geotechnical software specialist Rocscience for $535 million. The headline is another sizeable industrial-software transaction. The more important story is what Hexagon is trying to connect: continuous measurements of the physical world with models that predict how rock, soil and infrastructure will behave.
If that connection works, it could make geotechnical digital twins far more operational. If it does not, Hexagon will have paid a premium for an established software portfolio without resolving the difficult engineering, liability and interoperability questions between observation and prediction.
A premium price for trusted engineering software
Rocscience develops software for slope stability, finite-element analysis, tunnels, foundations, groundwater and related engineering problems. Its products include Slide2, Slide3, RS2 and RS3, and the company says customers use its software in about 125 countries.
According to Hexagon’s announcement, Rocscience is expected to approach $50 million in 2026 revenue, with more than 80% coming from annual recurring revenue and EBITAC margins above 40%. The $535 million enterprise value therefore represents roughly 10.7 times expected revenue. That is a substantial multiple, even for a profitable software company with sticky engineering workflows.
The deal is expected to close in the fourth quarter of 2026. Rocscience will join the Radar & Monitoring Division inside Hexagon’s Infrastructure & Geospatial business.
That organisational placement is revealing. Hexagon is not putting Rocscience beside generic design software. It is placing predictive modelling next to the instruments and platforms that observe ground movement.
The integration story did not begin with the acquisition
Hexagon describes a future in which sensor data automatically updates and calibrates engineering models. That remains a company claim, not a demonstrated end-to-end production capability. But the relationship has technical history.
Rocscience and Hexagon-owned IDS GeoRadar began integrating deformation-monitoring data in 2018. By 2019, engineers could bring live radar data into Slide3 and RS3. A later integration allowed Slide3 safety maps to be viewed with displacement information inside the IDS Guardian monitoring environment. The stated goal was already a “monitoring-to-modeling” workflow.
The acquisition therefore converts an existing partnership into a controlled product stack. Hexagon’s GeoMonitoring Hub can already combine radar, total-station, GNSS and third-party sensor data. Rocscience adds the analytical layer used to test possible failure surfaces, stress conditions and ground behaviour.
For an open-pit mine, the potential value is clear. Radar may detect accelerating movement on a slope, while a geotechnical model helps engineers interpret what that movement means under different geological and groundwater assumptions. Reducing the manual exchange between these systems could shorten the time between detection, interpretation and intervention.
Competition is already building connected subsurface platforms
Hexagon is not entering an empty market. Bentley’s Seequent business connects geological data and interpretation with GeoStudio and PLAXIS analysis through Seequent Central. Itasca competes in advanced geomechanical simulation with FLAC3D, 3DEC and related tools. In mine monitoring, Orica’s GroundProbe combines slope-stability radars with its MonitorIQ analysis platform and specialist services.
Rocscience has also been building its own broader platform. Since partnering with TA Associates in 2023, it has acquired DIANA for nonlinear structural analysis, 3GSM for rock-mass characterisation and blast analysis, 2SI for structural engineering, Rockfield for geomechanics, and Aquanty for surface-water and groundwater modelling.
Hexagon is consequently buying more than four familiar geotechnical applications. It is acquiring the beginnings of a multi-disciplinary engineering platform with access to structural, geological and hydrological workflows.
The hard part is governing the feedback loop
A live model is not automatically a reliable model. Sensor measurements contain noise and gaps. Numerical models depend on assumptions about materials, groundwater, geometry and boundary conditions. Automatically recalibrating a model can create false confidence if engineers cannot trace which observations changed which parameters.
That makes auditability critical. Customers will need version histories, uncertainty reporting, human approval gates and clear responsibility for automated recommendations. They will also want to know whether Hexagon will preserve support for third-party sensors and open data exchange, or use the acquisition to favour its own hardware.
Public practitioner reaction so far offers little independent guidance. Rocscience’s LinkedIn announcement attracted enthusiasm, but discussion was overwhelmingly congratulatory. Broader geotechnical forums show that engineers value Rocscience’s usability while relying on alternatives such as PLAXIS, GeoStudio and Itasca for different modelling requirements. That diversity matters because safety-critical modelling benefits from independent methods and cross-checks.
Hexagon has a credible technical rationale and an unusually clear integration starting point. What it has not yet shown is a delivery roadmap, pricing strategy or operational evidence that continuous sensor-to-model feedback improves decisions at scale.
At $535 million, that proof is now the central test of the deal.


